
 English
 Portuguese
Instalações e Reformas
A service ecosystem for selling, scheduling, and operating installations and home reforms with reliability across customer, partner, and internal journeys.
This case study reflects the point in my career where I moved from frontend ownership into broader technical leadership, working across backend, infrastructure, observability, release discipline, and product delivery for a business-critical ecosystem.
Project overview
An ecosystem built to connect customers, partner professionals, and Leroy Merlin operations around service delivery.
Instalacoes e Reformas was not just a single frontend application. It was a broader service ecosystem involving public pages, operational flows, partner onboarding, and internal tools that supported how installations and reforms were offered and executed.
The project required product thinking, technical consistency, and operational reliability because the experience touched different types of users and depended on stable communication between multiple services and teams.
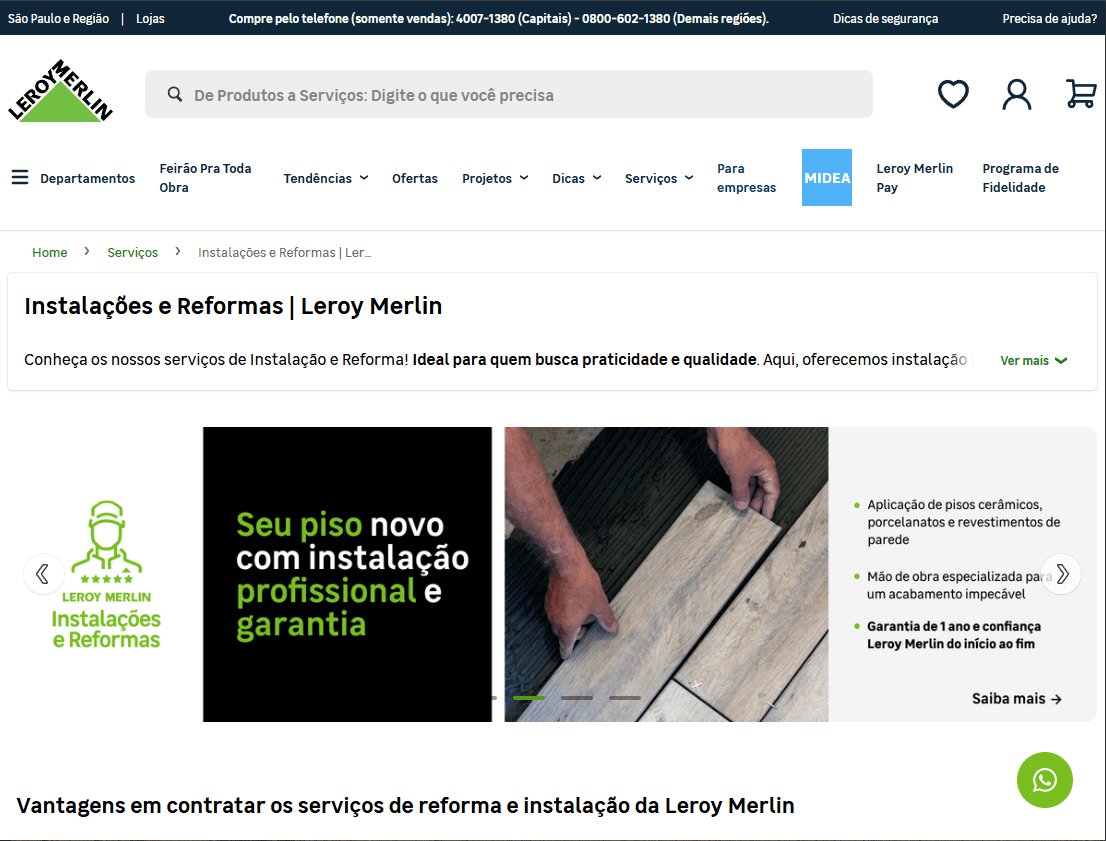
Public-facing service experience that helps explain the Instalações e Reformas offer and builds trust in the journey.
Business problem
The challenge was to make service operations understandable, scalable, and trustworthy for everyone involved.
Selling a service is more complex than selling a physical product. The platform needed to communicate trust, explain the service clearly, support operational rules, and create flows that worked for customers, business stakeholders, and partner professionals.
That meant reducing friction in acquisition and onboarding journeys while also giving the internal ecosystem enough structure to evolve without creating operational chaos.
Scope and complexity
The complexity came from scale, integration, and the fact that the ecosystem blended product, operations, and architecture concerns.
My work eventually touched more than 40 microservices and multiple frontend experiences. It was a context where changes in one part of the ecosystem could affect partner flows, customer communication, or internal operations.
The platform also had to support different environments, release flows, and technical decisions across a growing architecture, which made engineering discipline as important as feature delivery.
- Customer-facing flows and public pages connected to service acquisition
- Partner and onboarding experiences with operational dependencies
- Distributed architecture with frontend and backend services evolving in parallel
- Cross-team coordination involving product, engineering, and business stakeholders
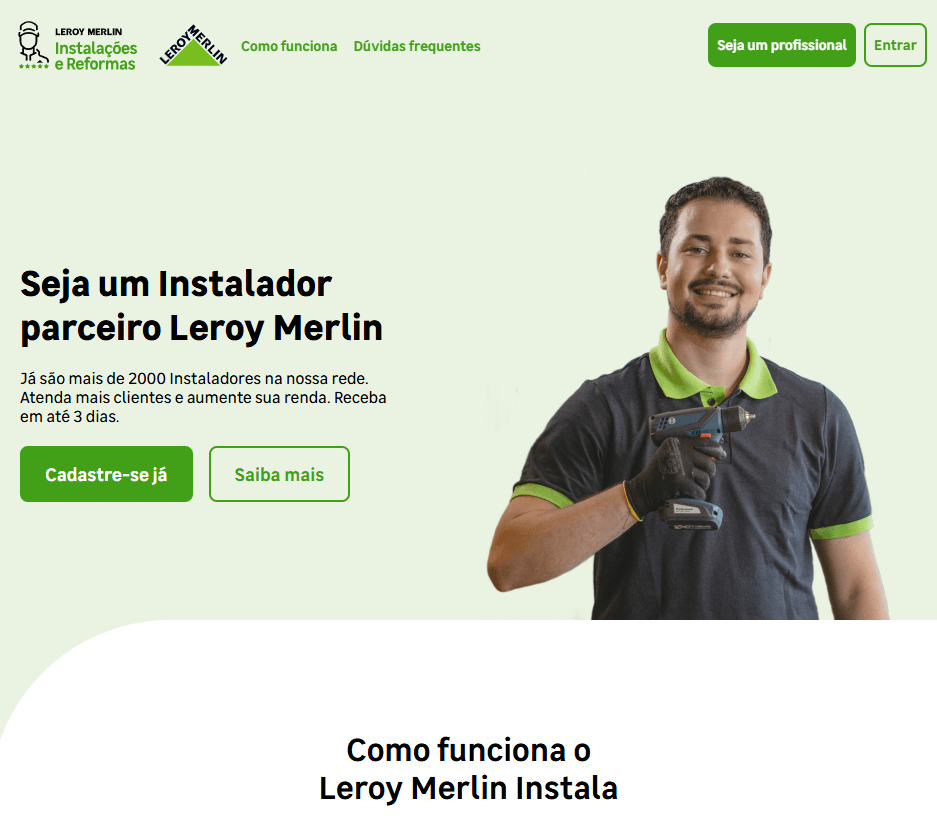
Operational and partner-facing context showing that the ecosystem extended beyond a simple landing page into onboarding and execution flows.
My role in the project
I started in the frontend and grew into a tech lead role with broader responsibility for delivery quality and technical direction.
Over time, I stopped being focused only on UI implementation and started supporting the ecosystem from a wider engineering perspective. I worked on frontend architecture, backend participation with Java and Spring Boot, infrastructure support on Google Cloud Platform, and observability initiatives.
I also supported technical decisions, helped organize codebases and folder structures, contributed to cleaner engineering standards, and worked closely with the team to keep the ecosystem maintainable while delivery kept moving.
- Technical leadership of a cross-functional team of about 12 people: 2 frontend, 2 backend, 2 full-stack engineers, 1 intern, PM, PO, agile coach, and QA
- Technical leadership for service evolution and cross-team delivery
- Hands-on contribution in React/Next.js frontend applications
- Backend support in Java and Spring Boot microservices
- Guidance on architecture, clean code, and implementation standards
Architecture and technologies
The ecosystem combined modern frontend delivery with backend services, observability, and release automation.
On the frontend, I worked with React-based applications, public pages, and operational experiences that needed clarity, performance, and maintainability. On the backend side, I participated in Java and Spring Boot services, helping with structure, clean code, and technical direction.
The operational side of the project also involved environment organization, semantic versioning, GitHub Actions workflows, Datadog monitoring, and support for event-driven evolution where service communication and long-term scalability mattered.
- Support for Google Cloud Platform environments and application lifecycle organization
- Datadog monitors for backend and frontend incidents and error visibility
- GitHub Actions workflows for unit tests, pull request feedback, deploy flows, and release discipline
- Technical support for diagrams, architecture discussions, and service communication improvements
Technologies and practices
Main contributions
My contribution was not limited to one layer of the stack. It was about making the ecosystem easier to evolve and safer to operate.
A large part of my work was improving engineering consistency, helping the team move faster with more confidence, and reducing ambiguity around how applications should be structured, delivered, and monitored.
- Supported architecture decisions across a distributed ecosystem with multiple services
- Helped define clean frontend and backend structures for scalability and maintainability
- Created GitHub Actions workflows for unit tests, pull request feedback, and deployment support
- Organized environments and release practices with semantic versioning and clearer delivery governance
- Created Datadog monitors to increase visibility into backend and frontend failures
Challenges
The project demanded technical depth and operational awareness at the same time.
One of the main challenges was balancing short-term business needs with long-term technical quality in an ecosystem with many dependencies. Another was making sure frontend, backend, and operational concerns were aligned enough that releases stayed reliable.
- Keeping consistency across many services, teams, and delivery cadences
- Improving observability and incident awareness in a distributed environment
- Supporting architecture evolution without blocking product demands
- Translating technical constraints into decisions that made sense for business and operations
Results and impact
The impact showed up in delivery maturity, technical reliability, and a more structured ecosystem.
When I took over technical leadership, the platforms were unstable and incidents were recurring, practically every week, to the point that the business team made stickers to joke about it on WhatsApp. With automated tests, observability, and release discipline, that pace dropped to roughly one incident every three months (estimate).
Just as important, the project consolidated my ability to connect code quality, platform decisions, and operational reality in an environment with strong business visibility.
- Near-weekly incidents dropped to roughly one every three months (estimate)
- Several applications went from zero test coverage to more than 80%
- Stronger release discipline with clearer workflows and versioning
- Better monitoring and faster visibility into backend and frontend problems
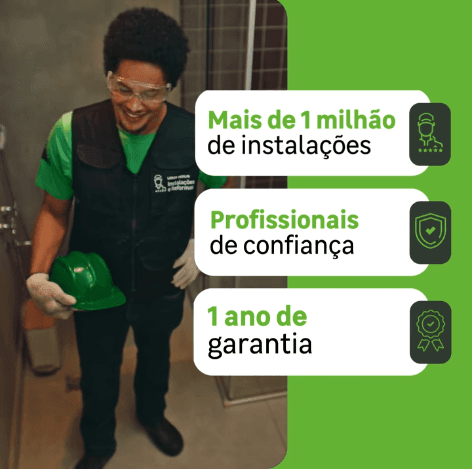
Service communication designed to reinforce credibility, scale, and confidence in the broader ecosystem.
Learnings
This was one of the experiences that most expanded my understanding of technical leadership.
I learned how much value comes from connecting architecture, observability, release discipline, and communication instead of treating them as separate concerns. I also strengthened my ability to support decisions beyond the frontend while staying practical and delivery-oriented.
- Leadership grows when you can connect product, engineering, and operations
- Scalability depends on standards, visibility, and decision clarity as much as on code
- Good technical direction reduces friction for both teams and business stakeholders
- Reliable delivery is built through systems, not isolated heroics
Let's talk
Looking for someone who can turn context into delivery
If you are hiring for a senior engineer or tech lead who combines technical depth, product awareness, and reliable execution, I am open to conversations.